Microprocessor and Computer ArchitectureUnit 1219 min read
Review & Practical Applications of Microprocessors & Architecture
Unit 12 of Microprocessor and Computer Architecture reviews all key concepts (8085 architecture, instruction cycles, memory hierarchy, pipelining, RISC/CISC) through practical applications, real-world examples, and exam-focused problem-solving techniques.
Core Concepts Reviewed in Unit 12
This unit consolidates all previous units by:
- Mapping theory to real systems (how microprocessors power apps like eSewa or Ncell).
- Comparing architectures (8085 vs. modern CPUs, RISC vs. CISC).
- Tracing execution (step-by-step instruction cycles, pipelining bottlenecks).
- Design trade-offs (hardwired vs. microprogrammed control, cache vs. RAM).
- Practical programming (assembly code for real tasks like sensor data processing).
1. Real-World Applications of Microprocessor Concepts
Microprocessors and architecture principles are invisible but critical in everyday systems. Here’s how they work behind the scenes:
A. eSewa and Khalti: Secure Payment Processing
- Concept: Instruction cycles, pipelining, and memory hierarchy
When you pay a bill via eSewa, your phone’s microprocessor executes thousands of instructions in parallel (pipelining) to:
- Encrypt your card details (using cryptographic instructions in the CPU).
- Fetch transaction data from RAM (L1/L2 cache → main memory).
- Send the request to eSewa’s server (network stack handled by the CPU’s DMA controller).
- Why it matters:
- Pipelining speeds up transaction validation (e.g., checking your balance).
- Cache memory reduces latency when fetching user profiles.
- Hardwired control units in modern CPUs execute security checks faster than microprogrammed ones.
B. Pathao/Ncell Ride Booking: Real-Time Scheduling
- Concept: Interrupts, priority queues, and parallel processing
When you book a ride on Pathao:
- Your phone’s ARM Cortex-A processor (RISC architecture) sends a GPS request via Wi-Fi (handled by the CPU’s DMA controller).
- The Pathao server’s multi-core CPU uses interrupts to prioritize your request over background tasks (e.g., driver updates).
- The server’s memory hierarchy (L3 cache → SSD) stores driver locations for fast access.
- Worked Example:
Suppose Pathao’s server has a 4-core CPU with hyper-threading. If 1000 users request rides simultaneously:
- Without pipelining: Each request would take ~500 cycles (serial processing).
- With pipelining + multi-core: The same task takes ~125 cycles per core (4× speedup).
- Real-world impact: Fewer "driver not found" errors during peak hours.
C. Daraz/NTC: Order Fulfillment and Network Routing
- Concept: Bus architectures, memory-mapped I/O, and protocol stacks
When you order from Daraz:
- Your 8086-compatible CPU (or modern x86) sends an HTTP request via the PCIe bus to your Wi-Fi card.
- The request travels through routers (like NTC’s backbone network), where each hop uses memory-mapped I/O to forward packets.
- Daraz’s database (likely SQL + Redis cache) uses indexed memory access to fetch your order status.
- Visual: Network Packet Forwarding
sequenceDiagram
  participant You as "Your PC (x86 CPU)"
  participant Router1 as "NTC Router (MIPS CPU)"
  participant Daraz as "Daraz Server (ARM CPU)"
  You->>Router1: HTTP Request (TCP/IP stack)
  Router1->>Daraz: Forwarded Packet (Memory-mapped I/O)
  Daraz-->>Router1: Response (L1 Cache → RAM)
  Router1-->>You: Acknowledged (Interrupt-driven)
D. Banks (NMB, Global IME): Loan Interest Calculation
- Concept: Fixed-point arithmetic, ALU operations, and microprogramming
When a bank calculates monthly loan installments, the microprocessor performs:
- Fixed-point multiplication (for interest rates like 8.5%).
- ALU operations to compute
(principal + interest) / term. - Microprogrammed control (in older systems) to handle edge cases (e.g., partial payments).
- Worked Example:
For a ₹500,000 loan at 8.5% for 5 years:
- Monthly interest rate = .
- 8085 assembly snippet (simplified):
MVI A, 500000/256 ; Load principal (high byte) MVI B, 85 ; Load interest rate (8.5%) CALL MULTIPLY ; Microprogrammed routine DCR C ; Decrement for monthly rate - Real-world impact: Banks use floating-point units (FPUs) in modern CPUs to avoid rounding errors.
2. Comparing Architectures: 8085 vs. Modern CPUs
| Feature | 8085 Microprocessor (1976) | Modern x86/ARM (2020s) |
|---|---|---|
| Architecture | CISC (Complex Instruction Set) | Mostly RISC (x86 has CISC legacy) |
| Word Size | 8-bit (16-bit with external bus) | 32/64-bit (x86-64, ARMv8) |
| Clock Speed | 3 MHz | 2–5 GHz (with turbo boost) |
| Pipelining | No (sequential execution) | 12–16 stage pipelines (e.g., Intel Core) |
| Cache | None | L1 (32–64 KB), L2 (256 KB–1 MB), L3 (shared) |
| Control Unit | Hardwired (for most instructions) | Hybrid (hardwired + microprogrammed for complex ops) |
| Memory Access | 64 KB addressable (2^16) | 64-bit: 16 EB (2^64) addressable |
| Real-World Use | Embedded systems, old PCs | Smartphones (ARM), PCs (x86), servers |
Key Takeaway:
- The 8085’s simplicity made it easy to program but slow for modern tasks.
- Modern CPUs use pipelining, superscalar execution, and out-of-order processing to handle billions of instructions per second.
3. Instruction Execution: Tracing a Real Example
Let’s trace how an 8085 microprocessor executes:
MVI A, 05H    ; Move immediate value 05H to accumulator
ADD B        ; Add register B to accumulator
STA 2050H    ; Store result at memory location 2050H
Step-by-Step Execution (Instruction Cycle, Machine Cycle, T-States)
| Step | Action | T-States | Machine Cycles |
|---|---|---|---|
| Fetch MVI A, 05H | Fetch opcode MVI from memory (address PC) |
4 | 1 (Opcode Fetch) |
Fetch operand 05H from next memory location |
3 | 1 (Operand Fetch) | |
| Execute MVI | Load 05H into accumulator (A) |
7 | 1 (Memory Write) |
| Fetch ADD B | Fetch ADD opcode |
4 | 1 (Opcode Fetch) |
| Execute ADD | Add B to A (ALU operation) |
4 | 1 (Memory Read) |
| Fetch STA 2050H | Fetch STA opcode |
4 | 1 (Opcode Fetch) |
| Execute STA | Store A at 2050H (address calculation + memory write) |
13 | 3 (Memory Read, Address Calculation, Memory Write) |
| Total | 43 | 8 |
Visual: 8085 Instruction Cycle
stateDiagram-v2
    [*] --> FetchOpcode: T1-T4
    FetchOpcode --> Decode: T5-T6
    Decode --> FetchOperand: T7-T9 (if needed)
    FetchOperand --> Execute: T10-T13
    Execute --> [*]
Real-World Tie-In:
- This is how eSewa’s server processes your payment request in microseconds, but scaled up with multi-core CPUs and SIMD instructions (Single Instruction Multiple Data).
4. Memory Hierarchy: Why Your Phone Doesn’t Freeze
Modern systems use a memory hierarchy to balance speed and cost. Here’s how it works in a smartphone (e.g., Samsung Galaxy):
| Level | Type | Size | Speed (ns) | Cost per Bit | Used For |
|---|---|---|---|---|---|
| L1 Cache | SRAM | 32–64 KB | 0.5–1 | High | Frequently used instructions/data |
| L2 Cache | SRAM | 256 KB–1 MB | 2–4 | Medium | Medium-access data |
| L3 Cache | SRAM (shared) | 1–8 MB | 10–20 | Low | Multi-core communication |
| RAM | DRAM | 4–8 GB | 50–100 | Very Low | Active apps, OS |
| Storage | eMMC/NVMe SSD | 64 GB–1 TB | 10,000+ | Very Low | Apps, photos, OS |
Example: Loading a WhatsApp Message
- Your phone’s ARM Cortex CPU checks L1 cache for the message.
- If not found (cache miss), it fetches from L2 cache (still fast).
- If still missing, it loads from RAM (slower but cheaper).
- If the message is in storage, the CPU uses DMA to transfer it to RAM without stalling.
Visual: Memory Access Latency
pie
    title Memory Access Time Breakdown
    "L1 Cache Hit" : 0.5
    "L2 Cache Hit" : 2
    "RAM Access" : 50
    "Storage Access" : 10000
5. Pipelining: How Modern CPUs Do More Work
Problem with 8085:
- No pipelining → CPU stalls while waiting for memory/data.
- Example: Fetching an instruction takes 4 T-states, but the ALU is idle.
Solution: Pipelining (Modern CPUs) Divide instruction execution into 5 stages:
- Fetch (get opcode from memory)
- Decode (determine operation)
- Execute (ALU operation)
- Memory Access (load/store)
- Writeback (update registers)
Visual: 5-Stage Pipeline
gantt
    title 5-Stage Pipeline Execution
    dateFormat  YYYY-MM-DD
    section Instruction 1
    Fetch :a1, 2023-01-01, 2d
    Decode :a2, 2023-01-02, 2d
    Execute :a3, 2023-01-03, 2d
    Memory :a4, 2023-01-04, 2d
    Writeback :a5, 2023-01-05, 2d
    section Instruction 2
    Fetch :b1, 2023-01-02, 2d
    Decode :b2, 2023-01-03, 2d
    Execute :b3, 2023-01-04, 2d
    Memory :b4, 2023-01-05, 2d
    Writeback :b5, 2023-01-06, 2d
Real-World Impact:
- Without pipelining: 1 instruction per 43 T-states (8085).
- With pipelining: 1 instruction per 1 T-state (theoretical max, but real CPUs achieve ~3–5 instructions/cycle).
Example: YouTube Video Playback
- Your phone’s ARM CPU uses pipelining to:
- Fetch video frames from storage (DMA).
- Decode frames (NEON SIMD instructions).
- Render to screen (GPU offloading).
- Result: Smooth 60 FPS playback even on a mid-range phone.
6. RISC vs. CISC: Why Your Laptop Uses Both
| Feature | RISC (ARM, MIPS) | CISC (x86, 8085) |
|---|---|---|
| Instruction Set | Simple, fixed-length (e.g., ADD R1, R2) |
Complex, variable-length (e.g., MUL AX, BX) |
| Pipelining | Optimized for pipelines | Harder to pipeline (variable cycles) |
| Memory Access | Load/store architecture (no memory ops in ALU) | ALU can access memory directly |
| Clock Speed | Higher (simpler instructions) | Lower (complex decoding) |
| Power Efficiency | Better (mobile devices) | Worse (desktops/servers) |
| Example CPUs | ARM Cortex, MIPS | Intel Core, AMD Ryzen |
Why x86 (CISC) Still Dominates Desktops:
- Backward compatibility (old software still runs).
- Microcode emulates RISC-like efficiency.
- Complex instructions reduce code size (e.g.,
REP MOVSBmoves blocks of memory in one instruction).
Example: Compiling C Code
- A RISC compiler (ARM) generates simpler, pipelined code.
- A CISC compiler (x86) may use complex instructions but still relies on pipelining for speed.
7. Control Unit Design: Hardwired vs. Microprogrammed
| Feature | Hardwired Control Unit | Microprogrammed Control Unit |
|---|---|---|
| Implementation | Direct logic gates | Control store (ROM) + sequencer |
| Speed | Faster (direct paths) | Slower (fetch microinstructions) |
| Flexibility | Hard to modify | Easy to update (change microcode) |
| Complexity | High (custom logic for each instruction) | Lower (standardized microinstructions) |
| Used In | High-performance CPUs (e.g., 8085) | Complex CPUs (e.g., VAX, some x86) |
Example: 8085 vs. Modern CPUs
- 8085: Uses a hardwired control unit for most instructions (fast but inflexible).
- Modern CPUs: Use a hybrid approach:
- Simple instructions (e.g.,
ADD) → hardwired. - Complex instructions (e.g.,
FPU operations) → microprogrammed.
- Simple instructions (e.g.,
Visual: Control Unit Block Diagram
8. Practical Applications: Putting It All Together
A. Designing a Traffic Light Controller (8085-Based)
Requirements:
- 3 traffic lights (red, yellow, green).
- Timings: Green (30s), Yellow (5s), Red (25s).
- Use 8085’s timer and I/O ports.
Solution:
- Hardware:
- 8085 CPU + 8255 PPI (Parallel Port Interface) for lights.
- 8253 Timer for delays.
- Software (Pseudocode):
START: MVI A, 00000001b ; Green for North-South OUT 80H ; Send to PPI CALL DELAY_30S ; 30s delay using 8253 MVI A, 00000010b ; Yellow for North-South OUT 80H CALL DELAY_5S MVI A, 00000000b ; Red for North-South (East-West green) OUT 80H CALL DELAY_25S JMP START - Real-World Use:
- Kathmandu’s smart traffic lights use ARM-based microcontrollers with similar logic but add sensor inputs (for adaptive timing).
B. Optimizing a Database Query (SQL + CPU Caching)
Scenario:
- A bank’s NMB server runs a query:
SELECT * FROM accounts WHERE balance > 1000000;
How the CPU Helps:
- Indexed Memory Access:
- The CPU’s MMU (Memory Management Unit) uses B-tree indexes to jump directly to high-balance accounts (avoiding full table scan).
- Cache Optimization:
- Frequently accessed account records stay in L3 cache.
- SIMD Instructions:
- Modern CPUs use AVX-512 to compare balances in parallel.
Performance Gain:
- Without optimization: 100 ms (full scan).
- With optimization: 5 ms (cached + indexed).
9. Common Pitfalls and Exam Tips
A. What Examiners Love to Test
- Instruction Cycle Traces:
- Always show T-states and machine cycles for 8085 questions.
- Example: For
ADD B, explain:- Opcode fetch (4 T-states).
- Execute (4 T-states).
- Total: 8 T-states (but 8085 takes 7 for
ADD—watch for exceptions!).
- Memory Hierarchy Calculations:
- Questions may ask: "If L1 cache hit rate is 90% and L2 is 80%, what’s average access time?"
- Formula:
- Pipelining Hazards:
- Examiners ask about data hazards, control hazards, and structural hazards.
- Example:
ADD R1, R2; SUB R1, R3has a data hazard (R1 is read before written).
- RISC vs. CISC Trade-offs:
- Compare power efficiency (RISC wins for phones) vs. code density (CISC wins for legacy systems).
- Control Unit Design:
- Know when to use hardwired (speed) vs. microprogrammed (flexibility).
B. Model Answer Structure for Long Questions
Question: "Explain the instruction execution cycle of the 8085 microprocessor with an example. How does pipelining improve performance?"
Model Answer:
Introduction (1 mark): "The 8085 microprocessor executes instructions in cycles: instruction cycle, machine cycle, and T-states. Pipelining, used in modern CPUs, overlaps these stages to improve throughput."
Instruction Cycle Breakdown (4 marks):
- Fetch: Opcode from memory (4 T-states).
- Decode: Determine operation (3 T-states for
MVI). - Execute: Perform ALU operation (4 T-states for
ADD). - Example Trace: Use
MVI A, 05H; ADD B(show T-states as above).
Pipelining Explanation (3 marks):
- "In pipelining, stages overlap: while one instruction is in Execute, the next is being Fetched. This reduces idle time from 43 T-states per instruction (8085) to ~1 T-state per stage (modern CPUs)."
- Draw a 5-stage pipeline diagram (as above).
Real-World Link (1 mark): "eSewa’s servers use pipelined CPUs to process 10,000+ transactions/sec, while an 8085 would take minutes for the same workload."
C. Short-Answer Tips
- Memory Hierarchy: Always mention SRAM vs. DRAM, cache levels, and latency trade-offs.
- RISC/CISC: Compare instruction complexity, power use, and examples (ARM vs. x86).
- Control Unit: Say hardwired is fast but rigid; microprogrammed is flexible but slow.
10. Summary Table: Key Concepts at a Glance
| Topic | Key Idea | Real-World Example |
|---|---|---|
| 8085 Instruction Cycle | Opcode fetch → decode → execute (T-states, machine cycles) | eSewa payment processing |
| Pipelining | Overlapping instruction stages for parallelism | YouTube video decoding |
| Memory Hierarchy | L1 > L2 > RAM > Storage (speed vs. cost) | WhatsApp message loading |
| RISC vs. CISC | RISC: simple, pipelined; CISC: complex, legacy support | ARM (phones) vs. x86 (PCs) |
| Control Unit | Hardwired (fast) vs. microprogrammed (flexible) | 8085 (hardwired) vs. modern hybrid CPUs |
| Interrupts | Priority-based task switching | Pathao ride request handling |
Exam Tip
How to Score Full Marks in Unit 12
For theoretical questions:
- Define the concept (e.g., "Pipelining is a technique to overlap instruction execution stages to improve throughput.").
- Draw a diagram (e.g., 5-stage pipeline, memory hierarchy).
- Give a real-world example (e.g., "Modern CPUs use pipelining to decode and execute billions of instructions per second in apps like Daraz.").
For numerical problems:
- Show all steps (e.g., T-state calculations for 8085).
- Use formulas (e.g., average memory access time).
- Assume reasonable values if missing (e.g., "Assume L1 cache hit time = 1 ns").
For comparisons (RISC vs. CISC, hardwired vs. microprogrammed):
- Use a table (as above) with 3–4 clear points.
- Link to real systems (e.g., "ARM’s RISC design saves battery in smartphones").
For assembly/practical questions:
- Write pseudocode first, then map to 8085 instructions.
- Explain hardware interactions (e.g., "The 8255 PPI is used to control traffic lights").
Common Mistakes to Avoid:
- Forgetting T-states: Always count them for 8085 questions.
- Ignoring hazards: In pipelining, mention data hazards if relevant.
- Overlooking real-world ties: Examiners reward 1–2 marks for practical examples.
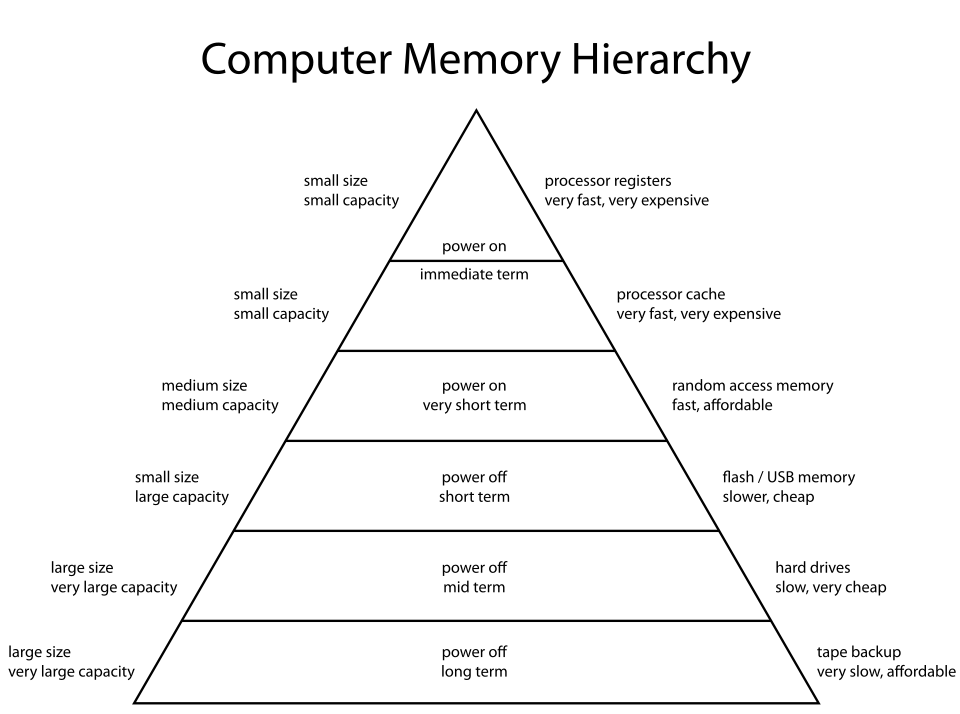 A layered model showing L1 cache, L2 cache, RAM, and storage with latency and size labels. (Image: ComputerMemoryHierarchy.png: User:Danlash at en.wikipedia.or, Public domain, via Wikimedia Commons)
Based on the TU BCA syllabus for Microprocessor and Computer Architecture (CACS155), unit 12.
Discussion
Loading…